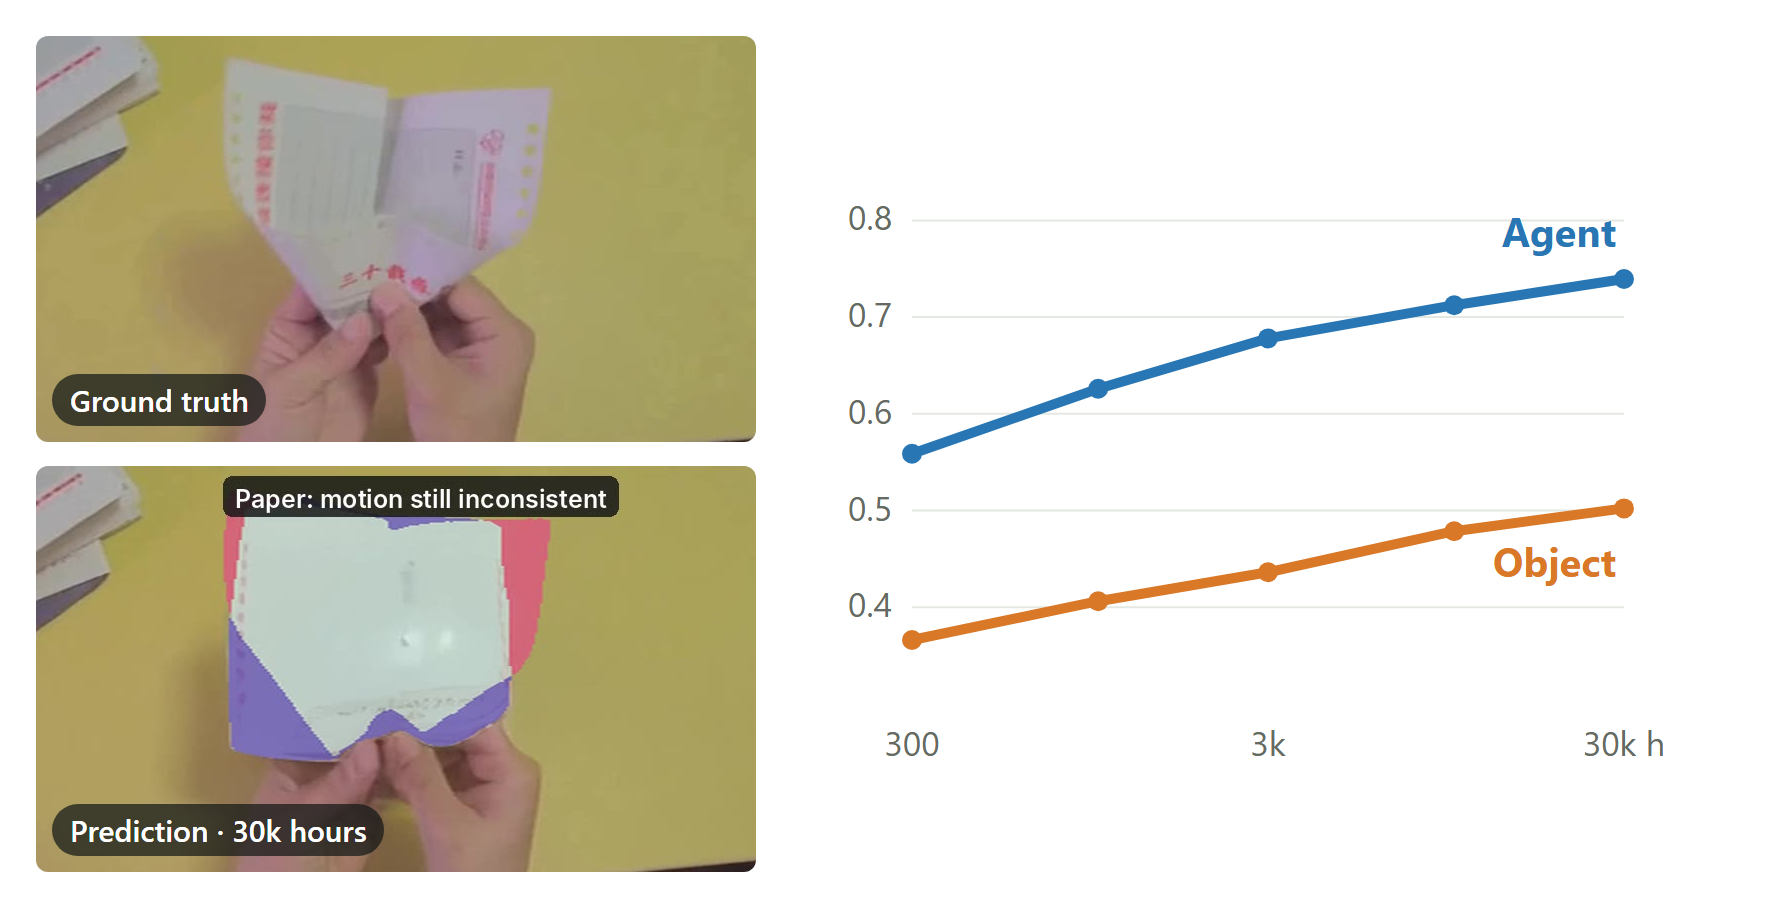
What 30,000 Hours of Ego-centric Video Does Not Teach
Scaling ego-centric human video brings agent modeling close to its limit, while the fidelity of the agent’s effects on objects converges far below it.
Computer Science · UIUC
Ph.D. student Computer Vision & Embodied AI
I build visual models that understand
and interact with the physical world.
I am a Ph.D. student at the University of Illinois Urbana-Champaign, advised by Prof. Yu-Xiong Wang. My research connects video generative models, 3D representations, and embodied intelligence.
I am interested in how models represent a changing world: generating coherent scenes, understanding object interactions, and learning representations that support robot control.
Previously, I worked on video world models at Toyota Research Institute and video generative AI at Google. I received my M.S. from UIUC and my B.S. from Zhejiang University.
01 / Research
From visual representations
to controllable worlds.
Scaling ego-centric human video brings agent modeling close to its limit, while the fidelity of the agent’s effects on objects converges far below it.
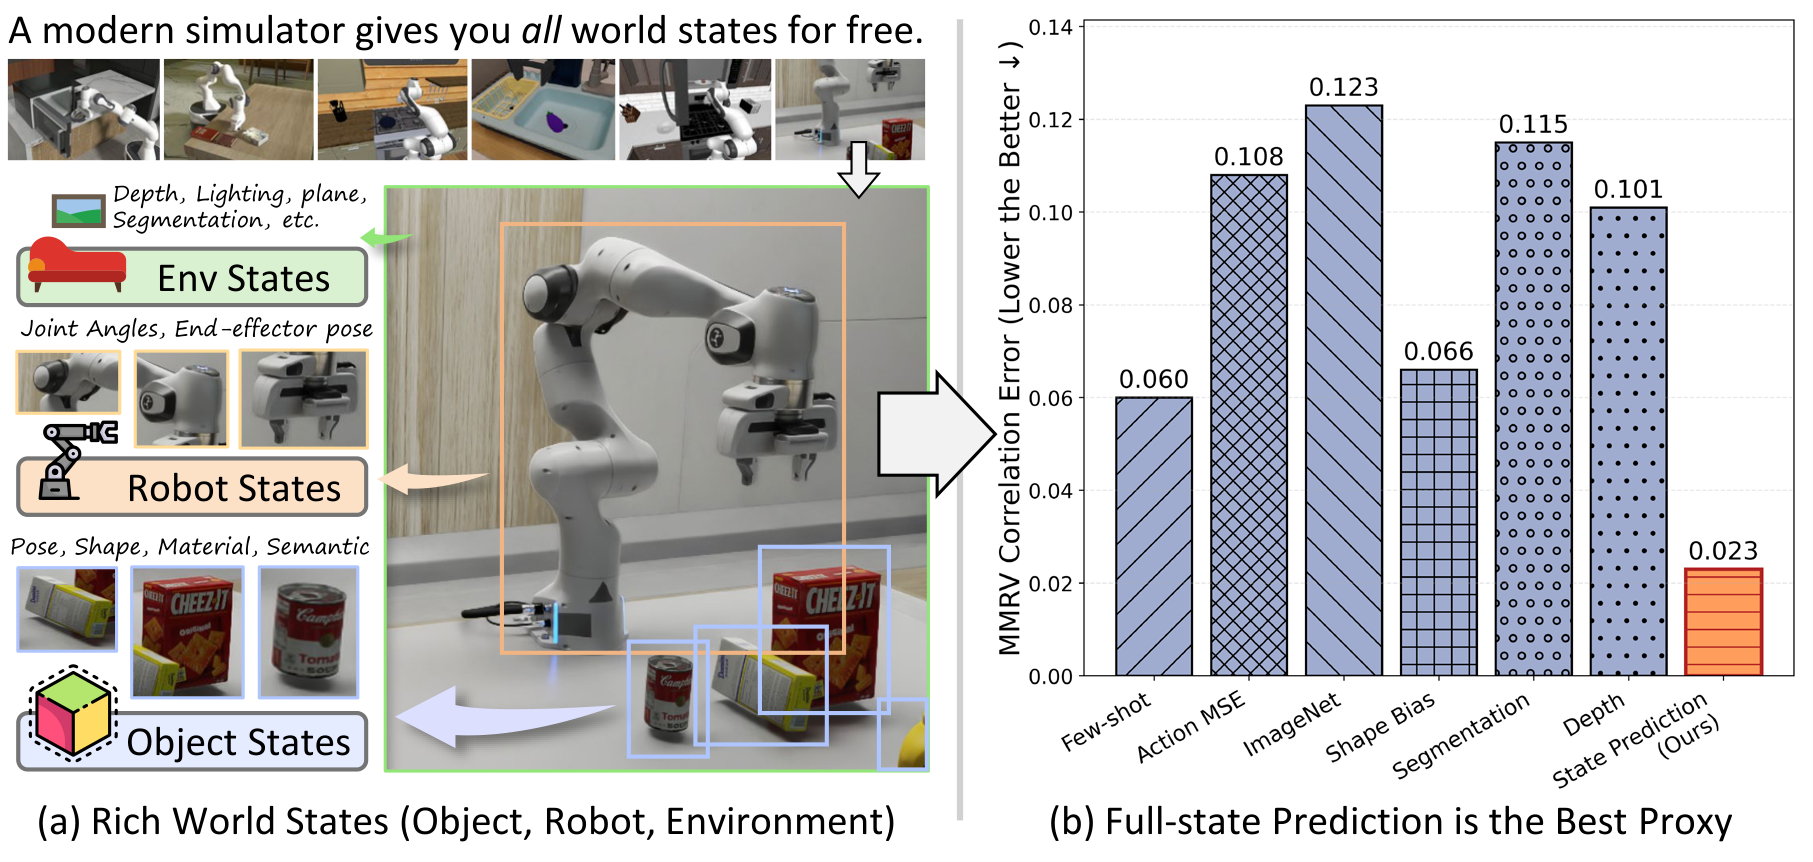
Predicting environment state from images provides a practical proxy for choosing visual representations for robot control.
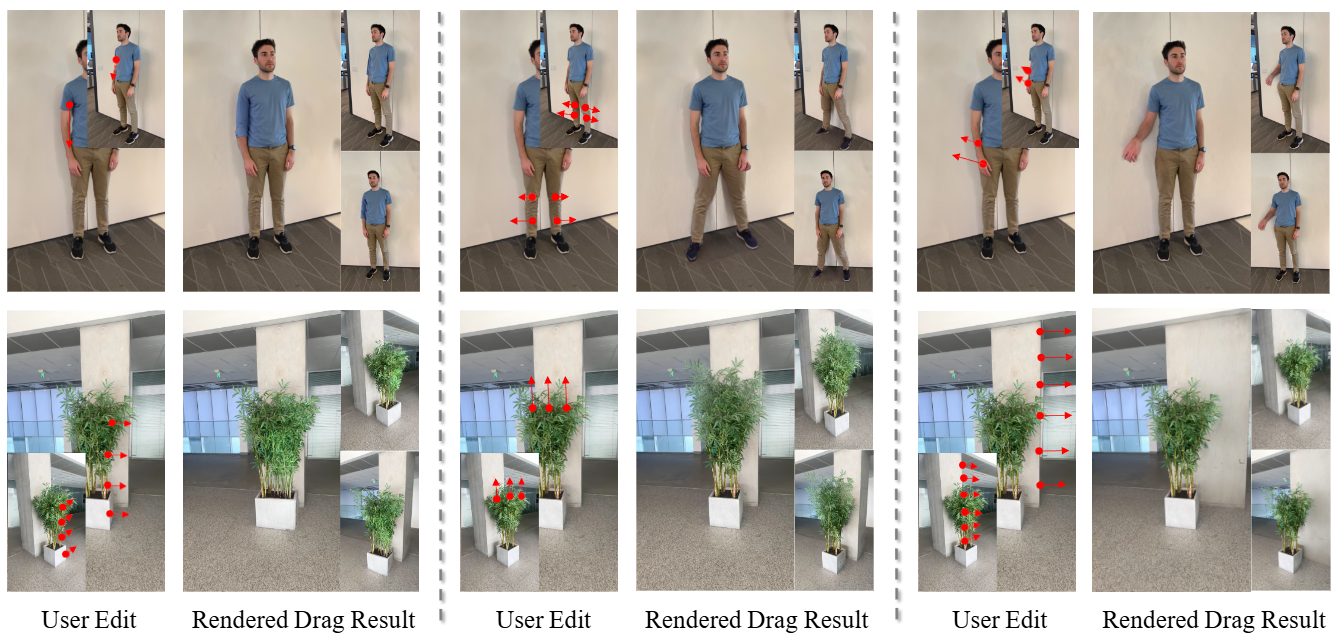
Intuitive point-based control for editing the geometry and appearance of 3D Gaussian scenes.
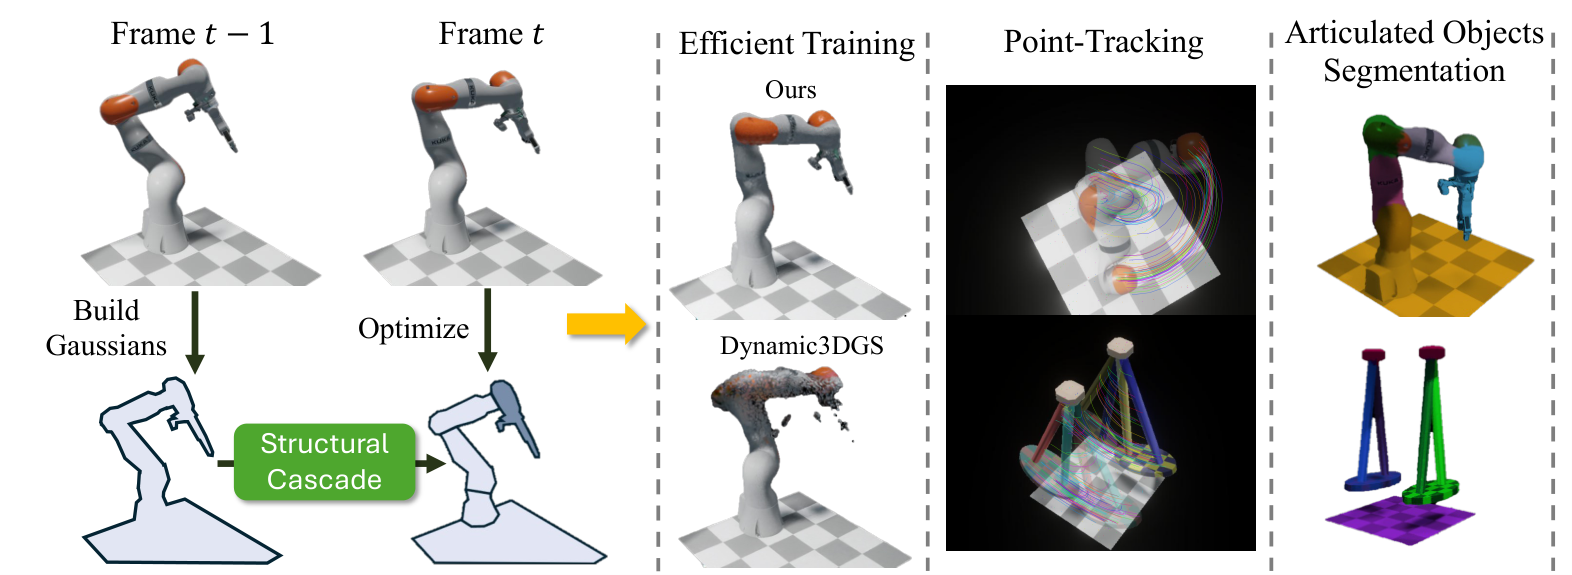
Cascaded optimization that follows the hierarchical structure of deformation, giving fast dynamic-scene modeling with point tracking and articulated-object segmentation for free.
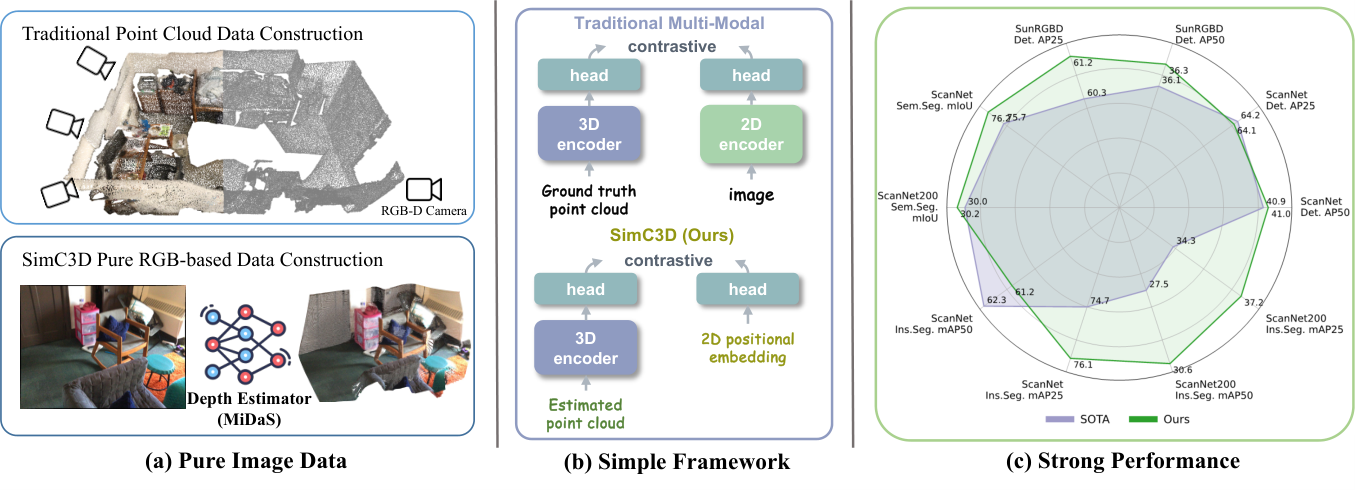
Contrastive 3D pretraining from RGB images alone, using estimated depth in place of scanned point clouds and a simple pure-3D framework.
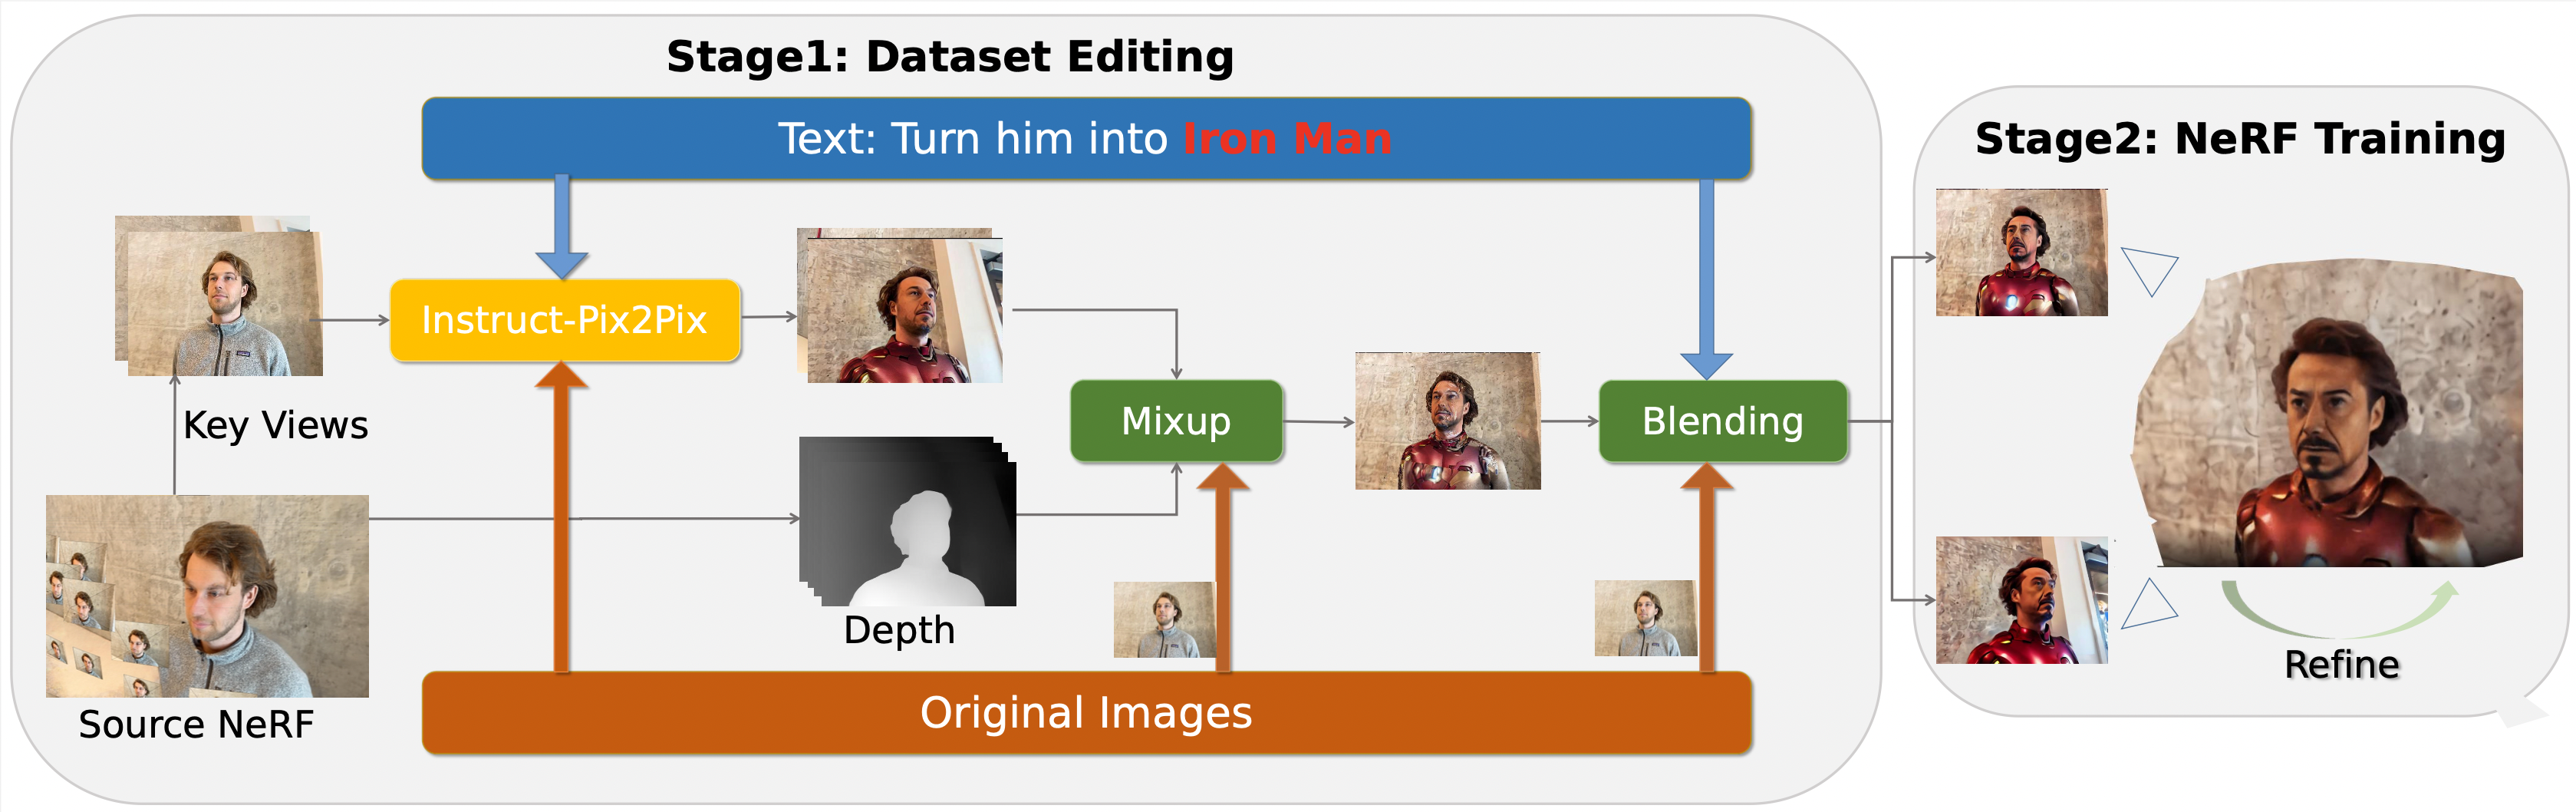
Text-guided 3D editing with geometric and learned regularization to keep edits consistent across viewpoints.
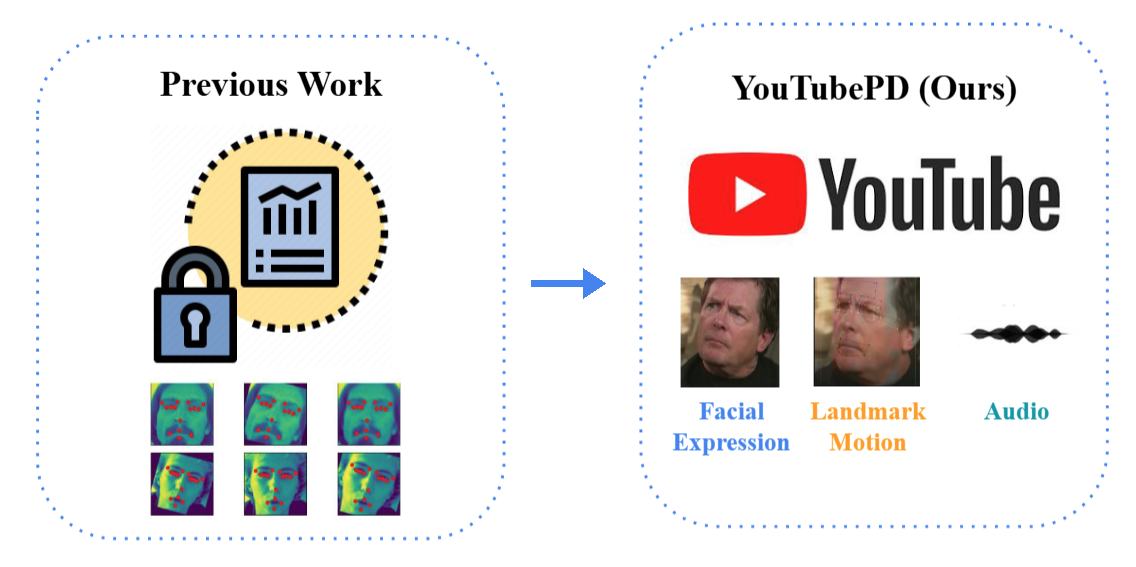
A public multimodal benchmark for Parkinson’s disease analysis built from YouTube videos, covering facial expression, landmark motion, and audio.
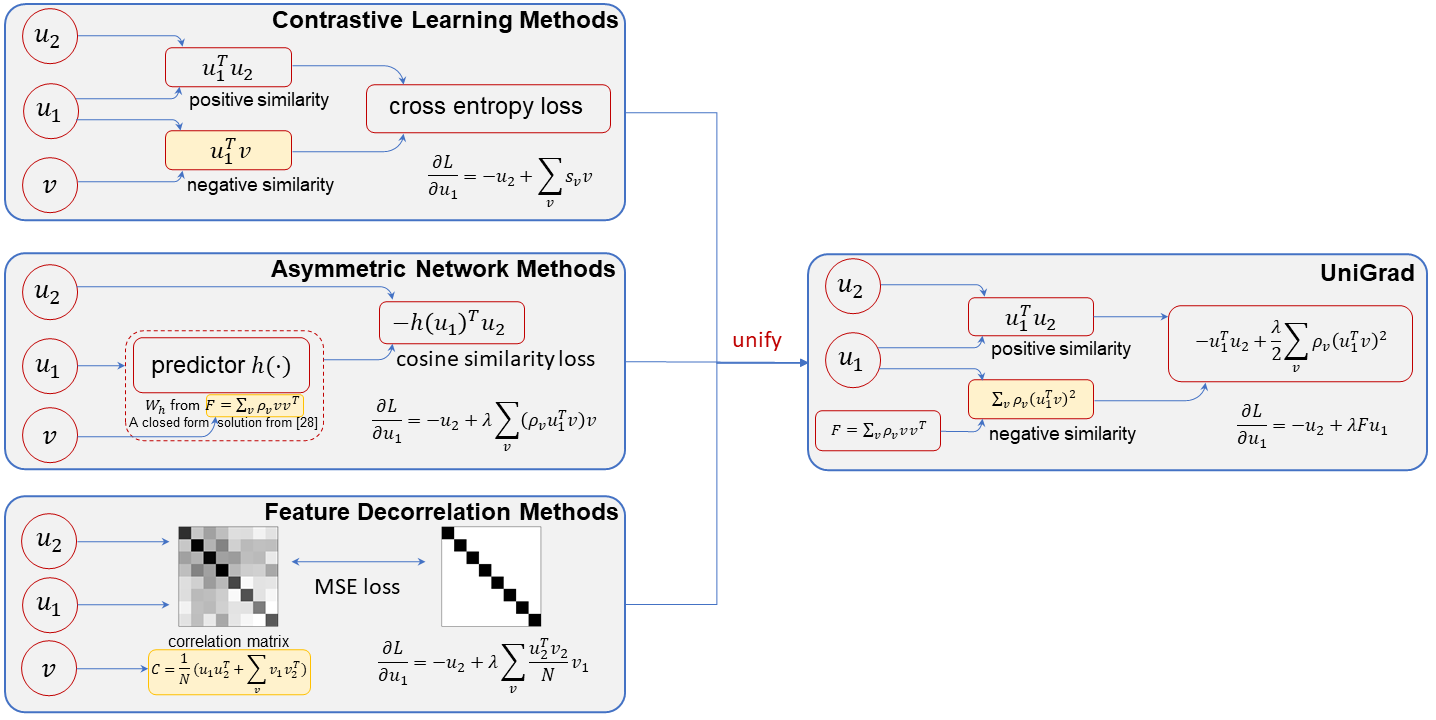
Contrastive, asymmetric-network, and feature-decorrelation methods share one gradient form, which yields UniGrad, a simple and effective objective.
* Equal contribution.
02 / Background
May – Aug 2026
Ph.D. Intern · Human Video World Models
Egocentric video generation, agent motion, and object interactions.
Jun – Dec 2025
Ph.D. Student Researcher · Video Generative AI
Video diffusion, spatial consistency, and world memory for 3D scene generation.
Dec 2023 – Sep 2024
Research Assistant
Visual understanding of geologic maps and multimodal learning for health.
Dec 2021 – Jul 2022
Research Scientist Intern
3D representation learning from RGB images.
May – Nov 2021
Research Scientist Intern
Siamese self-supervised learning and loss-function search.
2024 – Present
Ph.D. in Computer Science
Advisor: Yu-Xiong Wang
2022 – 2024
M.S. in Computer Science
2018 – 2022
B.S. in Computer Science and Technology
Ranked 1st of 186 students
03 / Contact
I’m always happy to discuss research in computer vision,
world models, and embodied intelligence.